
webclaw
Fast, local-first web content extraction for LLMs. CLI, MCP server, REST API, and SDKs for AI agents and RAG pipelines.
Ficha actualizada 10 nov 2026, 18:44 · upstream 10 nov 2026, 18:06 · release v0.7.3
Qué es webclaw
Descripción editorial construida a partir del repositorio, su documentación y sus señales de mantenimiento.
webclaw is a comprehensive toolset for extracting structured data from websites. It provides a Rust-based core with Python bindings, an MCP server for AI agent integration, and a hosted API. The tool handles HTML parsing, crawling, batching, mapping to structured formats (markdown, JSON), and LLM-ready summarization. It works locally without requiring API keys for basic operations, making it ideal for agents that need reliable web access. The CLI supports multiple output formats including markdown, text, JSON, and LLM-specific formats optimized for RAG pipelines.
- AI agent web access: Provide Claude, Cursor, or other MCP clients with clean page context without API keys
- RAG ingestion: Crawl documentation sites, help centers, blogs, and knowledge bases into structured format
- Competitor monitoring: Track pricing pages, changelogs, docs, and product pages across competitors
- Structured extraction: Convert messy web content into typed JSON for automated data pipelines
- Research workflows: Search the web, scrape results, summarize sources, and cite multiple documents
- Brand intelligence: Extract logos, colors, fonts, social metadata, and brand assets from company sites
- Local-first architecture with a pure Rust core that performs extraction without network I/O for basic operations
- MCP server enables seamless integration into AI agent workflows like Cursor, Windsurf, and other code assistants
- Supports multiple output formats including markdown, JSON, text, HTML, and LLM-specific formats optimized for RAG pipelines
- Batch processing with parallel execution allows efficient scraping of large numbers of URLs simultaneously
- Crawl mode discovers new pages automatically without manual URL entry, ideal for documentation sites
- Brand extraction tool extracts logos, colors, fonts, and social metadata in a single operation
- The hosted API requires an API key and may have rate limits or usage quotas
- Crawling deep into nested pages can be slow due to JavaScript rendering requirements on many sites
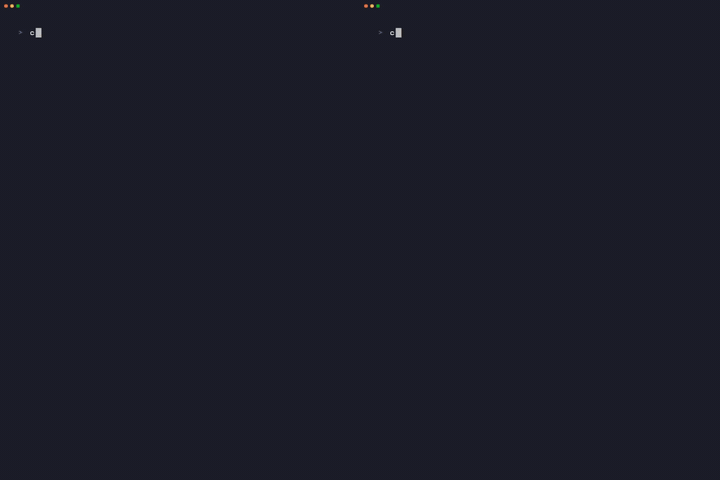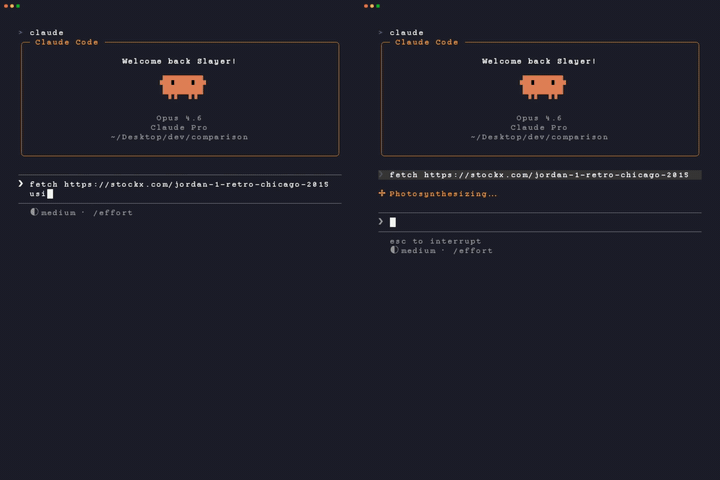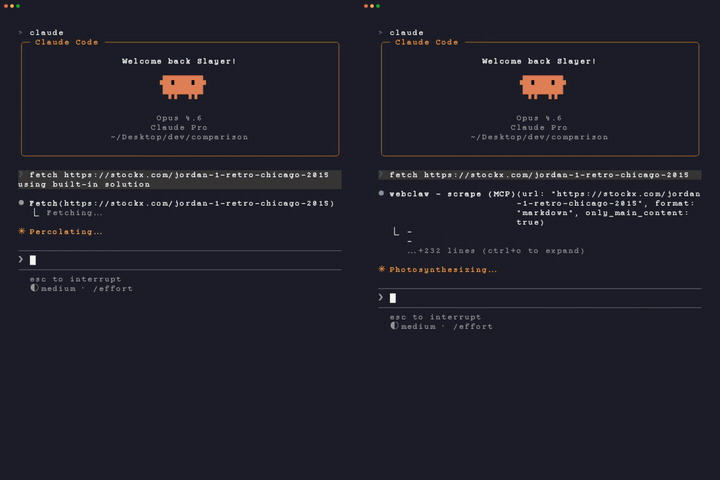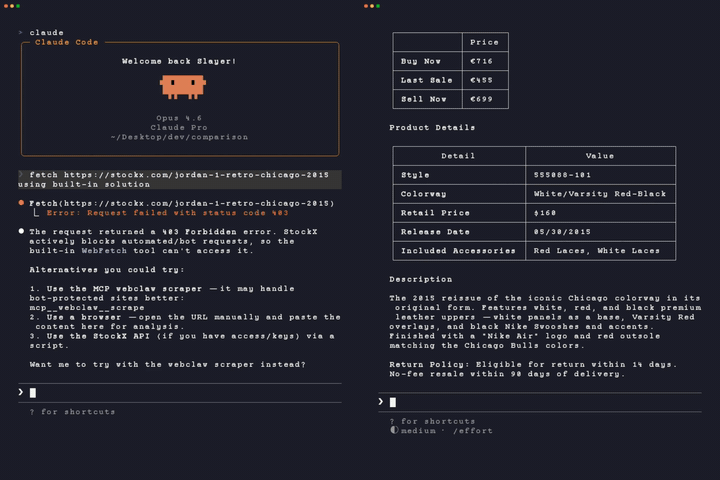
- Some modern websites use anti-bot measures that may block requests without proper headers or user-agent rotation
- PDF extraction is limited to text content only, not images or embedded documents
- The tool does not handle multi-language content natively; each language requires separate configuration
Capturas del proyecto
Imágenes reales detectadas en la documentación del repositorio.
Perfil de infraestructura
Estimación inicial derivada del repositorio y de los servicios detectados.
Despliegue detectado
Qué señales reales de instalación hemos encontrado.
Pendiente de la cola editorial R11-R6 con investigación verificable.
Stack y dependencias
Componentes inferidos a partir de manifests, configuración y documentación.
Puede sustituir a
Relaciones detectadas por el análisis del repositorio y su categoría.
Experiencia real de la comunidad
Ayuda a contrastar la estimación automática con instalaciones reales.
Todavía no hay datos comunitarios para este proyecto.